Generative AI Development.
Build production generative software that reasons and delivers.
AKREVON designs and engineers production-grade generative AI applications—combining state-of-the-art LLMs, structured outputs, deterministic guardrails, and responsive user interfaces.
MULTIMODAL INTELLIGENCE · FOUNDATION MODELS · LATENCY OPTIMISATION
PRODUCTION-READY CAPABILITIES
Production-ready generative ai development built for real-world use.
We transform frontier foundation models into reliable, high-throughput software components with strict SLAs and deterministic JSON outputs.

Production LLM Applications
End-to-end web and mobile applications leveraging state-of-the-art multimodal reasoning models with sub-second streaming.
Structured Output Engineering
Deterministic JSON schema generation, rigorous schema validation, and fallback parsing for error-free backend consumption.
Contextual AI Copilots & Assistants
Embedded workflow assistants that understand user state, historical interactions, and domain terminology.
Safety Guardrails & Content Moderation
Multi-layer defense protecting against prompt injection, jailbreaks, data leakage, and inappropriate outputs.
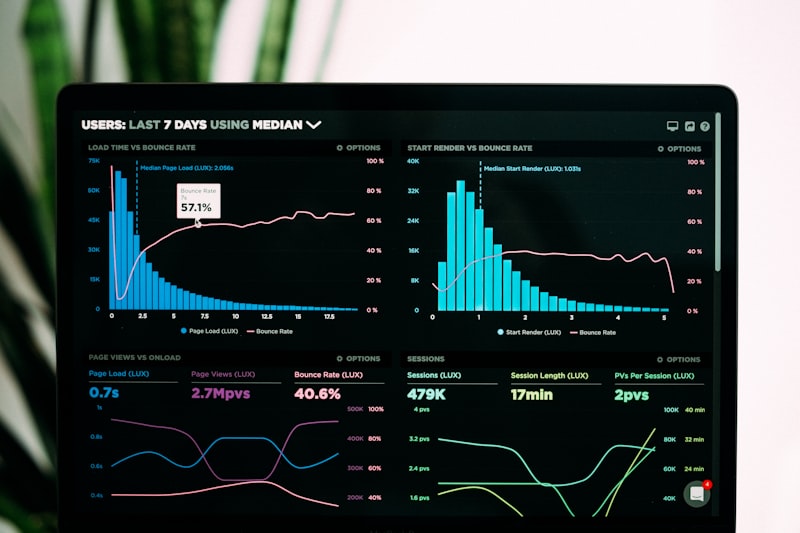
Automated Evaluation & Benchmarking
Continuous regression testing measuring answer accuracy, hallucination rates, tone consistency, and semantic drift.
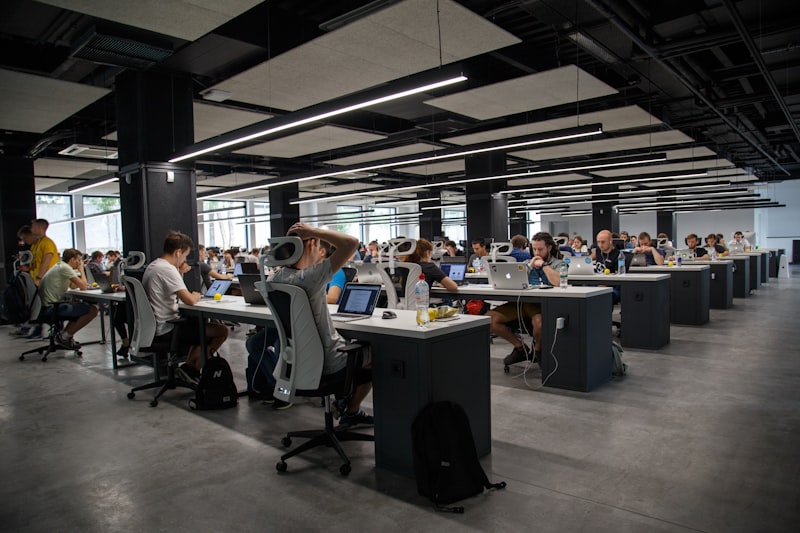
Production Telemetry & Observability
Real-time tracking of token consumption, latency distribution, cache hit rates, cost attribution, and user feedback loops.
PRODUCTION ARCHITECTURE
From model to production application.
Raw foundation models are probabilistic and brittle. AKREVON constructs the multi-tier engineering stack required to deliver deterministic, low-latency applications at enterprise scale.
Foundation Models
Frontier APIs & fine-tuned open-source weights
Selection and distillation across Claude, GPT, Gemini, Llama, and Mistral—matching task complexity with parameter size, latency, and cost.
Enterprise RAG
Grounded retrieval across proprietary knowledge
Hybrid dense/sparse vector search, metadata filtering, and semantic chunking ensuring answers reference verified internal documents without hallucinations.
Multimodal AI
Unified processing for vision, text, audio, and tables
Multimodal pipelines that extract structured data from PDF contracts, images, charts, and spoken customer interactions with high fidelity.
Orchestration & State
Dynamic execution loops, fallbacks, and streaming
Low-latency orchestration managing prompt templates, asynchronous parallel calls, retry cascades, and token streaming to client interfaces.
Semantic Guardrails
Deterministic safety, PII sanitization, and output schemas
Pre-flight and post-flight filters verifying structured JSON formats, stripping confidential PII, and blocking prompt injection exploits.
Automated Evaluation
Continuous regression benchmarking on golden datasets
Synthetic test suites measuring hallucination rates, factual precision, response latency, and token efficiency against production baseline runs.
Production Deployment
Containerized runtimes, GPU clusters, and observability
Autoscaling Kubernetes clusters, TensorRT/vLLM inference accelerators, blue/green deployment gates, and real-time token spend telemetry.
STRATEGIC GUIDANCE
Four decisions before building with generative AI.
Technical choices on foundation models, private data isolation, latency budgets, and continuous evaluation.

How We Build Generative AI Products
We engineer secure LLM applications, custom prompt pipelines, deterministic structured outputs, semantic guardrails, and automated regression evaluation suites.
Why Build with Generative AI
State-of-the-art foundation models unlock unstructured data synthesis, instant reasoning, autonomous drafting, and multimodal document understanding.

Why Generative AI for Your Product
Generative capabilities differentiate products by automating complex manual workflows, enabling hyper-personalized interfaces, and multiplying user productivity.

Why AKREVON for Generative AI
We build enterprise-grade generative systems with strict hallucination controls, cost-optimised token routing, and private data isolation.
FREQUENTLY ASKED QUESTIONS
Generative AI Development, answered.
Which foundation models does AKREVON recommend?+
We select models based on your task requirements: Claude 3.5 Sonnet for deep coding and reasoning, GPT-4o for multimodal speed, Gemini 1.5 Pro for massive context windows, and LLaMA 3 for private on-premise execution.
How do you prevent hallucinations in generative applications?+
We enforce strict grounding via RAG, configure low-temperature generation, employ dual-pass validator models, and require source citations for every factual claim.
Can you integrate generative AI into existing mobile apps?+
Yes. We have specialized native mobile engineering squads who build streaming SSE clients with native Swift and Kotlin interfaces.
How is pricing and token consumption monitored?+
We instrument OpenTelemetry and Langfuse/Helicone proxies to give you real-time visibility into cost per user, token efficiency, and cache hit rates.
Architect production AI with AKREVON.
Discuss enterprise architecture, vector database selection, token latency budgets, and security parameters with our principal AI engineers.