DevOps.
Reliable environments, automated operations and deep observability for scaling products.
DevOps is the bridge between software development and stable, predictable production operations. AKREVON engineers Infrastructure-as-Code, container orchestration, blue/green zero-downtime releases, and real-time observability so your engineers ship code faster with fewer firefighting incidents.
QUALITY CAPABILITIES
Automate infrastructure, streamline deployments, and ensure 99.9% uptime.
We design reliable production environments, automate operations, and implement observability so your teams deliver software with velocity and calm.
Infrastructure-as-Code (Terraform / OpenTofu)
Modular, version-controlled cloud infrastructure codified in Terraform, eliminating manual provisioning and configuration drift.
Container & Fleet Orchestration
Docker optimization, lightweight container images, multi-stage builds, and orchestration via Kubernetes, ECS, or Cloud Run.
Zero-Downtime & Canary Releases
Blue/green and canary release strategies with automated health checks, progressive traffic shifting, and instant rollback capability.
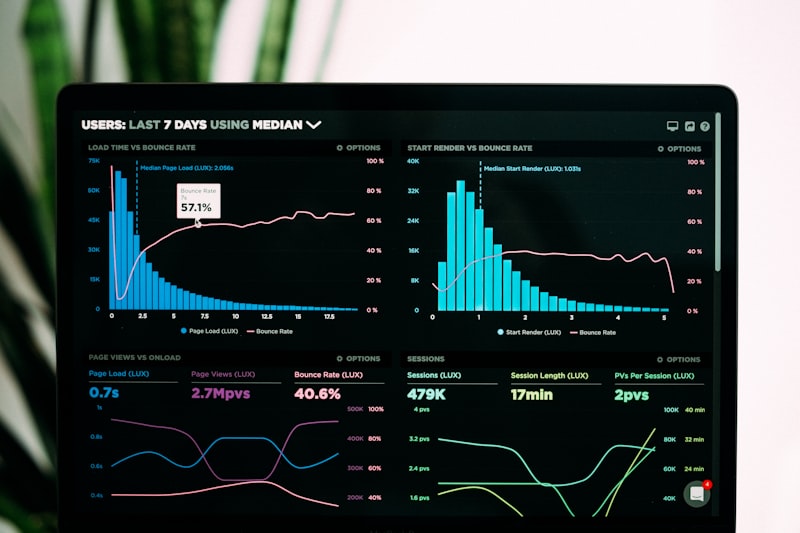
Full-Stack Observability & Telemetry
Unified logging, metrics, and distributed tracing with Prometheus, Grafana, OpenTelemetry, Datadog, or Sentry.
Multi-Environment Parity & Previews
Isolated development, staging, and ephemeral preview environments matching production configurations and network behaviors.

Site Reliability Engineering (SRE) & Runbooks
Service Level Objectives (SLOs), automated healing, clear on-call runbooks, and blameless post-mortem operational frameworks.
RELEASE GOVERNANCE
Before scaling delivery
Four operational decisions that separate high-velocity engineering teams from chaotic firefighting.
Can any developer spin up a full, reproducible environment on demand?
If creating a new environment requires days of manual DevOps tickets, your release velocity is throttled. We build Infrastructure-as-Code blueprints that allow spinning up clean, fully functional preview environments with a single command.
What is our Mean Time to Recovery (MTTR) when a bad release occurs?
Bugs will inevitably escape to production. The measure of operational maturity is how quickly you can revert. A zero-downtime blue/green deployment pipeline allows instant rollback to the previous healthy build within 30 seconds.
Do our alerts represent actual user impact or just noisy background warnings?
When alerts fire continuously for non-critical warnings, engineers ignore them. We structure alerting around user-impacting symptoms (elevated 5xx rates, checkout errors, latency spikes) rather than CPU utilization blips.
How are database migrations handled during zero-downtime releases?
Running destructive database migrations during an application update causes immediate downtime. We enforce the Expand-and-Contract migration pattern, ensuring database schemas remain backward-compatible across versions.
DELIVERY LIFECYCLE
How We Build DevOps Foundations
A pragmatic, scalable operational modernization that empowers your engineers to ship with confidence.
Infrastructure & Workflow Audit
We analyze current deployment friction, cloud configurations, manual steps, and operational bottlenecks across your teams.
IaC & Container Fleet Standardization
We codify all infrastructure into modular Terraform and build optimized, production-hardened Docker containers.
Zero-Downtime Deployment Engine
We implement blue/green deployment orchestration with health probes, canary verification, and instant rollback triggers.
Observability & Runbook Enablement
We deploy centralized dashboards, configure high-signal alert rules, author production runbooks, and train your engineering team.
Why DevOps Matters as Products Scale
Modern DevOps turns operations from a slow bottleneck into an unstoppable competitive delivery advantage.
10x Faster Deployment Frequency
Empower developers to safely ship small, incremental updates multiple times a day instead of high-risk quarterly releases.
Drastically Reduced Downtime (MTTR)
Automated blue/green deployments and instant rollbacks reduce incident recovery time from hours to under 60 seconds.
Eliminate Developer Burnout
Stop weekend deployment panics and late-night firefighting by building deterministic, self-healing infrastructure.
ENGINEERING ADVANTAGE
Why AKREVON for DevOps
Senior operations architects who build simple, maintainable systems without over-engineering.
Pragmatic Architecture, No Bloat
We do not install complex tools just because they are trendy. We build the simplest, most reliable architecture that matches your scale.
Zero-Downtime Standard
We engineer zero-downtime blue/green and rolling releases as the default standard for all production applications.
Complete Knowledge Transfer
We document every Terraform module, record architectural walkthroughs, and mentor your engineers so your team owns the stack.
DevOps answers
Ready to engineer rock-solid quality into your release?
Partner with AKREVON to build comprehensive automated test suites, stress-test performance boundaries, and deploy zero-defect release pipelines.